What it is
Overview
DeepSpeed is an open-source training optimization library from Microsoft that makes billion-parameter models trainable on hardware that would otherwise run out of memory. The core innovation reviewers name is ZeRO — Zero Redundancy Optimizer — which partitions model states across GPUs and offloads to CPU RAM when needed. Not an AI model itself; it's infrastructure. The audience is ML researchers and deep learning engineers training models at scale — the kind who need to fit a 175B-parameter model on eight GPUs instead of eighty.
At a glance
Usability & Quality overview
Best for
- large-scale multi-GPU training
- memory-efficient model scaling
- PyTorch-based research workflows
Watch out for
- single-GPU misuse
- manual configuration overhead
- slowdowns in offload-heavy setups
Real product, not a wrapperIndependent product
DeepSpeed provides proprietary ZeRO memory optimization technology that enables training billion-parameter models on limited GPU memory — a capability ChatGPT cannot replicate. It automates complex model parallelism and memory offloading workflows without requiring manual per-step configuration. This is foundational infrastructure for large-scale AI training, not a wrapper around existing LLMs.
Strong evidenceQuality score
DeepSpeed optimizes large-scale AI training with memory-saving ZeRO and parallelism, but setup can require manual tuning.
This score is our editorial judgment, computed automatically from the sources, weights, and dates shown above. It reflects the data we could verify as of November 16, 2026, not a guarantee or statement of fact about DeepSpeed. Third-party ratings and quotes belong to their original platforms and authors. Thin data lowers our confidence label, and we say so instead of guessing. Work on DeepSpeed? Dispute any datapoint and we will review it, publish your response, and correct verified errors.
PricingFree
Individual plan details haven't been verified yet — they'll appear here on the next data refresh.
Community feedback
Aggregated reviews
Ratings and quoted comments below are aggregated from third-party sources and reflect those users' views, not SearchTools.ai's.
What reviewers talk about
themes inside the Sentiment pillar — not score ingredients
74Output Quality15 mentions
“Both EleutherAI's gpt-neox and the BigScience project use DeepSpeed under the hood, probably because DeepSpeed still remains the best component for training large models. So really dependent on your scale if DeepSpeed is still your answer, or if you can get away with these native PyTorch alternatives. Things are slowly moving into PyTorch upstream such as the ZeRO redundancy optimizer but from my experience the team behind DeepSpeed just move faster. There is also fairscale from the FAIR team ”
“I’d recommend trying pytorch + deepspeed. Deepspeed has a lot of different features that help with model parallelism. In your case zero offload would let you (efficiently) offload model states to cpu memory, which should let you run the sizes you are targeting.”
“DeepSpeed is a deep learning framework for optimizing extremely big (up to 1T parameter) networks that can offload some variable from GPU VRAM to CPU RAM. Using fp16 precision and offloading optimizer state and variables to CPU memory I was able to run DreamBooth training on 8 GB VRAM GPU with pytorch reporting peak VRAM use of 6.3 GB. The drawback is of course that now the training requires significantly more RAM (about 25 GB). Training speed is okay with about 6s/it on my RTX 2080S. DeepSpeed ”
“I've been reading up on ZeRO-Offload since the paper was published last week – in this blog post and below I've written up a few introductory notes on what it is, when it's useful, how it can be used and how it works. Let me know if I forgot anything important or got something wrong. What is ZeRO-Offloading? ZeRO-Offloading is a way of reducing GPU memory usage during neural network training by offloading data and compute from the GPU(s) to CPU. Crucially this is done in a way that provides high”
42Reliabilitythin data · 7 mentions
“Hey there! I've also encountered issues with GPU memory limitations. Using DeepSpeed is a great idea for distributing layers across multiple GPUs. Regarding your observation about higher GPU usage with two GPUs, it's unexpected behavior. Typically, DeepSpeed should optimize resource utilization. Double-check your DeepSpeed configuration and make sure it's set up correctly. If the issue persists, consider reaching out to the DeepSpeed community for further assistance.”
“I've been trying to fine tune the llama 2 13b model (not quantized) on AWS g5.12x instance which has 4*24gb A10GPUs, and 192gb ram. I'm also using PEFT lora for fine tuning. I've been trying to fine-tune it with hugging face trainer along with deepspeed stage 3 because it could offload the parameters into the cpu, but I run into out of memory errors irrespective of the batch size or my sequence length. In the deepspeed configuration file I have given the offload optimizer and offload param to cp”
“Hi everyone! I'm struggling with the common issue of having limited GPU memory. We have multiple 16GB GPUs, and I wanted to distribute the layers of my model across these GPUs to facilitate training. To achieve this, I decided to use the DeepSpeed library. After configuring the Accelerate file, I managed to get it running. However, I've noticed that the GPU usage is actually higher when using two GPUs compared to running the model on just one. Is this expected behavior, or have I misunderstood h”
“Both EleutherAI's gpt-neox and the BigScience project use DeepSpeed under the hood, probably because DeepSpeed still remains the best component for training large models. So really dependent on your scale if DeepSpeed is still your answer, or if you can get away with these native PyTorch alternatives. Things are slowly moving into PyTorch upstream such as the ZeRO redundancy optimizer but from my experience the team behind DeepSpeed just move faster. There is also fairscale from the FAIR team ”
31Ease of Usethin data · 6 mentions
“So i want to full parameter fintune mistral 7b model on my custom dataseti have access to 4 A10G gpus which they have 96 GB in totaland maybe 8 A100G 40GB which makes 320 GB in total using deepspeed 3 which as i understand can distroute the training on multiple GPUS Im trying to use this code here : trainer.py which it tested on 8 A100 80 GPUs ( which i don't have ) however the configuration for deep speed are here: compute_environment: LOCAL_MACHINEdebug: falsedeepspeed_config:deepspeed_multino”
“FWIW and anyone looking in the future, I hit this same issue. It turns out that because I was using Trainer() and TrainerArguments() with DeepSpeed. You HAVE to call TrainerArguments BEFORE calling .from_pretrained(). This initializes deepspeed zero init and sets up the configurations necessary to distribute your model (assuming zero stage 3) to all your workers. It turns out that TrainerArguments is calling that init inside.”
“anyone tried this on windows? when running pip install --upgrade diffusers the first issue that I've encountered was missing convert-caffe2-to-onnx.exe I have solved this by running pip install onnx-caffe2 now the issue I have is missing f2py.exe I've googled and it seems that I need to (re)install numpy, will see how it goes, but if someone has it working on windows - I would like to know what the did :) edit, to install f2py you just need to install anaconda, and then: conda install ”
“There isn’t anything to learn with Accelerate, it’s just a whole bunch of IF statements that occasionally breaks because it isn’t heavily tested at scale (eg if you’re using both deepspeed and accelerate and enable gradient checkpointing, which implementation will it use?? Find out, I guess). The standard for big multi node jobs is the Kubeflow PyTorch operator or some equivalent, Slurm or MPI work fine too at the end of the day it’s just about setting environment variables. All distributed tr”
Watch & learn
Video content
YouTube YOUTUBE633 views
Scaling Large Frontier Models Training with DeepSpeed - Zhipeng Wang PyTorchCon NA Keynote
PyTorch9 days ago
 YOUTUBE118 views
Why Your GPUs Are Still Running Out of Memory (ZeRO & FSDP Explained)
Softmaxedd1 month ago
 YOUTUBE56 views
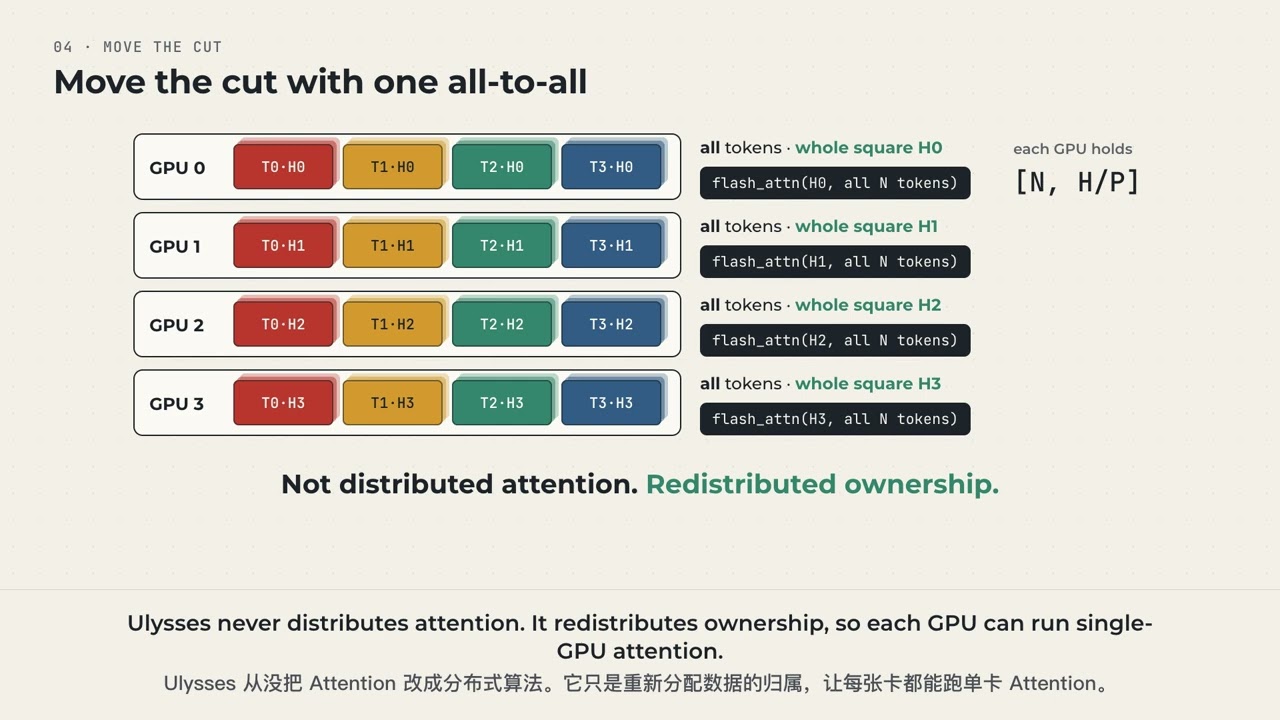
DeepSpeed-Ulysses Explained: Sequence Parallelism Is One Transpose
zencat_tube26 days ago
 YOUTUBE44 views
#487 Hugging Face Accelerate and DeepSpeed: One Training Script for Any Hardware
LetsLearn-AI-12312 days ago
Capabilities
Key features
Developer Tools
Provides utilities that help programmers build, test, and ship software faster
The honest take
What users love & flag
Distinct themes surfaced across user reviews — each grounded in real review text, ranked by how often it comes up.
Questions
Frequently asked
What is DeepSpeed?
DeepSpeed is an open-source deep learning optimization system that enables training of extremely large AI models with 100+ billion parameters. It addresses GPU memory limitations through innovations like ZeRO (Zero Redundancy Optimizer) and has powered some of the world's largest language models including Megatron-Turing NLG (530B parameters), BLOOM (176B parameters), and Jurassic-1 (178B parameters).
Is DeepSpeed free to use?
Yes, DeepSpeed is completely free and open source. It's part of Microsoft's AI at Scale initiative and welcomes community contributions under a Developer Certificate of Origin agreement.
What is ZeRO and how does it help with training large models?
ZeRO (Zero Redundancy Optimizer) is DeepSpeed's core memory optimization technology that partitions optimizer states, gradients, and parameters across multiple devices instead of replicating them. This enables training of trillion-parameter models by dramatically reducing the memory footprint on individual GPUs, allowing researchers to train models that would otherwise exceed single-device memory capacity.
What frameworks does DeepSpeed integrate with?
DeepSpeed has official integrations with major deep learning frameworks including Hugging Face Transformers, Hugging Face Accelerate, PyTorch Lightning, and MosaicML Composer. These integrations allow users to incorporate DeepSpeed optimizations into their existing workflows without major code changes.
What is ZeRO-Infinity and when would I use it?
ZeRO-Infinity is an advanced DeepSpeed feature that breaks GPU memory limitations by offloading optimizer states, gradients, and parameters to CPU and NVMe memory. This is particularly useful when training models that exceed even the combined memory of multiple GPUs, enabling training at scales previously impossible.
Can DeepSpeed help with model inference or just training?
DeepSpeed supports both training and inference. DeepSpeed Inference provides efficient deployment for large transformer models, while compression technologies like ZeroQuant enable post-training quantization to reduce model size and improve inference performance.
What is 3D-Parallelism in DeepSpeed?
3D-Parallelism is DeepSpeed's approach that combines three types of parallelism strategies: data parallelism, model parallelism, and pipeline parallelism. This comprehensive parallelization strategy enables efficient distribution of training workloads across thousands of devices while maximizing hardware utilization.
What is DeepSpeed-Chat used for?
DeepSpeed-Chat is a component designed specifically for RLHF (Reinforcement Learning from Human Feedback) training, which is the technique used to align large language models with human preferences. This makes it particularly relevant for organizations building ChatGPT-style conversational AI systems.
Who should use DeepSpeed?
DeepSpeed is designed for AI researchers, machine learning engineers, and organizations working on large language models and massive neural networks. It's particularly valuable for teams that need to train models exceeding the memory capacity of individual GPUs or want to accelerate training of billion-parameter models.
Compare DeepSpeed
Compare with another toolMore Like This